Your Data Pipeline Cost Guide: How to Benchmark & Budget for Consulting Engagements
data pipeline cost guide, data engineering consulting, snowflake vs databricks cost, cloud cost optimization
A mid-market data pipeline draws its budget from three places: cloud infrastructure, platform licensing, and the engineers and consultants who build and run it. That last category is usually the largest line item, which is why consulting rates deserve as much scrutiny as your cloud bill - see data engineering consulting rates 2026 for the listed range across the 86 firms in the Data Engineering Companies Index and how to compare quotes. This guide covers the five layers of total cost of ownership, the three biggest cost drivers, and a five-step framework for building a budget you can defend to finance.
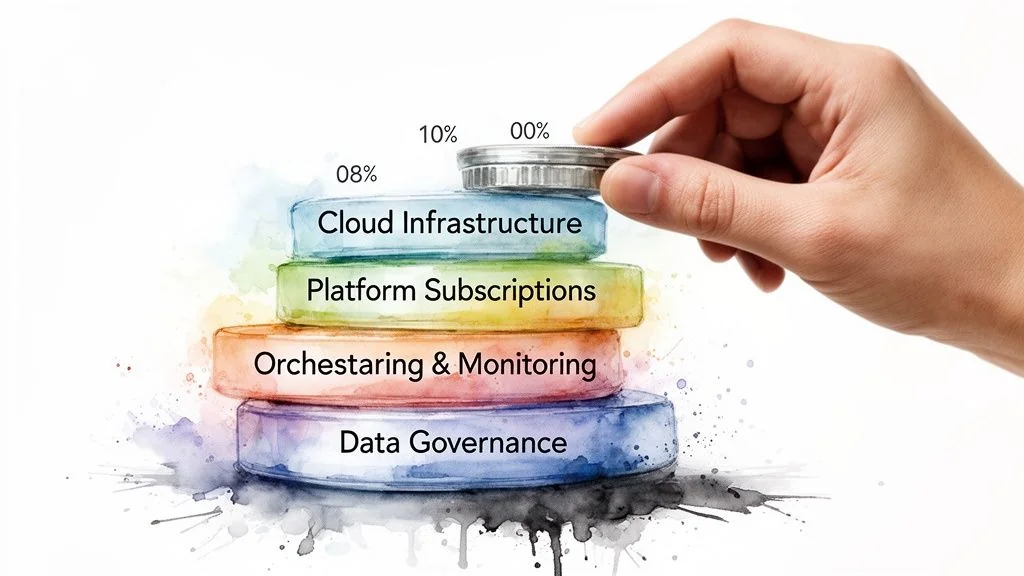
What are the five layers of data pipeline total cost of ownership?
Total cost of ownership for a data pipeline runs across five areas: cloud infrastructure, platform licensing, engineering and consulting talent, orchestration and monitoring tooling, and data governance. Missing any one of them in your budget is what turns a tight estimate into a mid-year overrun.
Unaddressed technical debt in a pipeline is what inflates every one of those categories over time - a schema that never got documented or a job that never got refactored shows up later as extra engineering hours, extra compute, or both.
People (your engineers and consultants) represent the largest share of the budget. Governance and specialized tooling, by contrast, are consistently underfunded, and that gap tends to surface later as data quality problems and access-control gaps.
What are the three largest cost drivers behind data pipeline spend?
When a data pipeline budget spirals, the cause is almost always one of three factors: cloud infrastructure spend, platform licensing, or talent costs. Get a handle on these three and the rest of the budget mostly falls into place.
What drives cloud infrastructure costs?
Data egress, the cost of moving data out of your cloud or between regions, is usually the biggest surprise on a cloud invoice, bigger than compute or storage. Egress gets missed during architecture design and then shows up prominently on the first real bill.
Each cloud provider presents its own cost challenges:
- AWS: A vast service portfolio with pricing that’s hard to model. Data egress fees are a common source of budget surprises when they aren’t explicitly accounted for upfront.
- Azure: The default choice for Microsoft-centric organizations. Pricing for services like Azure Data Factory spans multiple billing dimensions - DIUs and vCore-hours - that need to be tracked separately.
- GCP/BigQuery: Generally cleaner pricing and strong performance. The risk is cost escalation from high query volumes when SQL isn’t optimized for BigQuery’s slot-based architecture.
How do Snowflake and Databricks licensing costs work?
Both platforms bill by consumption rather than seat count, so understanding the billing unit matters more than reading the price sheet. Snowflake’s credit model is consumed by virtual warehouse uptime; Databricks’s DBU model is tied to cluster runtime.
The outcome is the same either way: a poorly written, long-running query burns budget. It just shows up as a different line item depending on which platform you’re on.
How much does engineering and consulting talent cost?
Talent is the single largest line item in most data engineering budgets, and it’s a straightforward supply and demand problem - the pool of engineers with real production experience on modern platforms hasn’t grown as fast as demand for them. If you want to put a number on what a strong team actually returns, data engineering ROI measurement walks through how to track it against your own baseline instead of an industry average.
Pricing varies widely across the 86 firms profiled in the Data Engineering Companies Index, and the directory’s rate fields are unverified estimates, so get written quotes before you budget. For the listed range and a breakdown by firm type and delivery model, see data engineering consulting rates 2026.
A blended team that pairs onshore oversight with nearshore or offshore delivery can stretch a budget further without giving up quality - the rates guide above breaks down which firm types are set up to support that model.
Which consulting engagement model fits your project?
Selecting the wrong engagement model is the fastest way to blow your budget. The commercial structure has to match how well-defined your project’s scope and goals already are, or you end up paying for your consultant’s learning curve, or locked into a scope that stopped being relevant weeks ago.
When does time and materials pricing make sense?
With time and materials (T&M), you pay for hours worked plus direct costs. This gives you maximum flexibility, which makes it the right fit for projects with an undefined path - architectural discovery, agile development, anything where nobody yet knows exactly what “done” looks like. The tradeoff is that the risk sits with you: if scope expands or unexpected complexity shows up, you pay for the extra time.
Contractual tip: mandate a “right to replace” clause for underperforming resources, and negotiate a “not to exceed” (NTE) cap on hours to keep weekly burn in check.
When does a fixed-price engagement make sense?
A fixed-price agreement sets one price for a well-defined scope of work. This works when requirements are locked - a data migration from a legacy system to Snowflake where source and target schemas are already mapped, for example. Risk shifts to the consulting firm, which gives them a direct incentive to work efficiently.
Red flag: be wary of a vendor pushing a fixed-price deal on a project with a lot of unknowns. Either they’ve baked a large contingency buffer into the price and you’re paying for it anyway, or they’re setting you up for aggressive change orders on anything not spelled out explicitly in the original SOW.
When does an outcome-based agreement make sense?
This is the most aligned engagement model: a significant portion of consultant payment ties directly to hitting specific, measurable business goals - reducing data processing costs by a set percentage, or hitting a defined data quality score, for example.
It builds a real partnership, but it requires high trust and metrics mature enough to verify the outcome cleanly. It works best for optimization projects where ROI is directly measurable.
How do you build a data-driven pipeline budget in five steps?
A defensible number ties every dollar to a specific business outcome. Five steps take you from an abstract estimate to a data-backed proposal:
-
Baseline current costs. Audit every dollar you currently spend: pull your cloud bills from AWS, Azure, or GCP, tally software licenses for Snowflake, Databricks, or Fivetran, and review every active consulting agreement. That gives you a factual starting point instead of a guess.
-
Scope the future state. Define the “why” behind the project. What specific business outcome drives it - a new data product, self-serve analytics for marketing, something else? Tying the technical work to a real outcome is what makes the eventual budget defensible.
-
Estimate platform and infrastructure costs. Model costs using official pricing calculators from your cloud and data platform vendors. Run a few scenarios for compute, storage, and data transfer so you understand how usage actually translates into fees.
-
Calculate engineering effort. Budget for the people. Break the project into phases - discovery, design, build, test, deploy - estimate sprints or person-weeks for each, and price each phase using written quotes for whichever engagement model you’ve chosen.
-
Add a contingency buffer. No project goes exactly as planned. Add 15-20% to the total estimate. It covers the technical hurdles and scope adjustments that show up on almost every project, and it signals to finance that you’ve thought this through.
A modeling tool turns these five steps into an actual number: adjust inputs like project timeline or team composition and see the total cost move in response. Model your own scenario with the data engineering cost calculator.
How does FinOps keep pipeline costs under control?
Managing dynamic, consumption-based cloud costs against a static annual budget is a losing battle. FinOps is the discipline of tracking that spend close to real time instead of reconciling it once a quarter. A spreadsheet can’t catch an inefficient query or an over-provisioned cluster burning money as it happens - only active monitoring can.
From manual tracking to automated cost control
Monthly spreadsheet reviews can’t keep pace with consumption-based billing. More teams are shifting toward automated anomaly detection that flags an unexpected spike in compute or storage the day it happens, instead of at the end of the billing cycle. Architectures with heavy cross-region data transfer are a recurring source of surprise cloud bills, and idle or over-provisioned resources routinely account for a meaningful share of total spend at organizations that haven’t automated cost oversight yet.
Core FinOps strategies for data pipelines
Applying FinOps means implementing specific practices that change how your team operates, not just watching a dashboard.
-
Automated showback and chargeback: This creates accountability. Attribute cloud costs automatically to the specific teams, projects, or products that generated them. When engineers see the direct financial impact of their code, they write more efficient code.
-
Continuous resource rightsizing: Your workloads aren’t running at peak all the time. Use monitoring tools to continuously track resource utilization, and automatically scale down or pause idle or oversized compute clusters and virtual warehouses.
-
Reserved instances and savings plans: For predictable, baseline workloads like daily ETL jobs, don’t pay on-demand prices. Committing to reserved capacity with your cloud provider cuts compute costs substantially - check your provider’s own pricing calculator for the exact discount at your commitment level.
These practices move cost management from a monthly review toward continuous monitoring, and they make cost awareness part of how your engineering team already works instead of a separate finance exercise.
What’s the fastest way to get pipeline costs under control?
Three moves deliver the fastest results: audit what you’re already spending against the budget framework above, score your team’s FinOps maturity honestly, and model your next project’s total cost before you go ask for budget.
Step 1: Audit current spend
Establish a clear baseline. Use the budget framework above to audit your current data stack spend in full, then line up actuals against the cost layers for cloud, platforms, and engineering. This exercise alone tends to surface your top three cost drivers and expose the outliers that need urgent attention.
Step 2: Evaluate FinOps maturity
Get your data and finance teams in a room for an honest assessment. Review your current cost management practices against the FinOps strategies above. Are you actually rightsizing resources, or letting them run? Do you have showback in place? This conversation reveals the gap between where you are and where you need to be. Explore Snowflake cost optimization next if warehouse spend is where your biggest gap sits.
Step 3: Model your next project’s TCO
Stop making budget requests based on gut feelings. For your next major data initiative, use the data engineering cost calculator to model total cost of ownership. Plugging in your project specifics generates a defensible estimate that accounts for platform fees, engineering work, and contingency.
Data Pipeline Cost FAQs
How much should a data pipeline cost?
There’s no single number - it depends on data volume, pipeline complexity, and your team’s size and location. For a fuller cost breakdown by pipeline type and project scope, see the data pipeline cost estimation guide.
The allocation across categories matters more than the total. A reasonable starting split looks like:
- Engineering & consulting: 40-60%
- Data platform licensing (Snowflake, Databricks): 15-25%
- Cloud infrastructure (AWS, Azure, GCP): 15-20%
- Orchestration & monitoring tools: 5-10%
- Data governance & quality tools: 5-10%
A significantly different split is worth investigating - it usually signals an imbalance somewhere upstream.
What is the biggest hidden cost in data pipelines?
The biggest hidden cost is inefficient engineering. It inflates every other cost category, showing up as poorly designed architecture that burns cloud credits, or as engineers spending hours on manual fixes instead of automation.
An inefficient team costs more in salary and also drives up platform and infrastructure spending through avoidable rework. That’s why choosing the right delivery partner is one of the highest-impact financial decisions on a data engineering project.
How can I justify the cost of a new data pipeline?
Lead with value rather than cost: frame the investment around total cost of ownership and return on investment, and connect it to specific business outcomes.
Build your business case around three questions:
- What new revenue does this data make possible?
- What operational costs get eliminated by automating manual reporting?
- What’s the financial risk of making decisions on stale or inaccurate data?
When you can show the pipeline brings in new revenue, removes manual cost, or reduces the risk of decisions made on bad data, getting leadership buy-in gets easier.
Stop guessing. Get clear, defensible numbers for your next data project. DataEngineeringCompanies.com provides detailed firm profiles, and a suite of tools to help you select the right data engineering partner with confidence. Find your expert match today.
- Part of our guide: Data Pipeline Architecture →

Researched & written by
Peter Korpak , Chief Analyst & Founder
Data-driven market researcher with 20+ years in market research and 10+ years helping software agencies and IT organizations make evidence-based decisions. Former market research analyst at Aviva Investors and Credit Suisse.
Previously: Aviva Investors · Credit Suisse · Brainhub · 100Signals
- Accenture779000 people · unverified
Large enterprises running multi-cloud transformations across AWS, Azure, and GCP simultaneously, where a single integrator needs to own the full program.
Listed, not reviewed - Adastra2000+ people (see scope)
Enterprise data, cloud, and analytics work across financial services, insurance, retail, and other sectors. Ask for references from similar projects.
Reviewed - Aimpoint DigitalNot verified
Consider Aimpoint for programs using Snowflake, Databricks, and dbt. It lists credentials for all three; ask for relevant references and the names of the proposed consultants.
Reviewed
More in Data Pipeline Architecture
Top Data Engineering Managed Services for 2026
Compare data engineering managed services models and pricing structures, with a vendor scorecard and red flags for Snowflake and Databricks partners.
Data Reliability Engineering A Guide for CTOs
Learn what Data Reliability Engineering (DRE) is, why it matters, and how to implement it. A complete guide for leaders evaluating data engineering partners.
Fivetran vs Airbyte: An Enterprise TCO Analysis for 2026
Fivetran vs Airbyte for enterprise teams: total cost of ownership, reliability, connector fit, and the operating model each tool puts on your team.